
Updated 9 October 2026. Top innovative AI inference vendors to shortlist include Groq, Cerebras, Fireworks AI, Together AI and Modal. The right choice depends on your model, latency target, concurrency, deployment control and total cost. This guide compares documented capabilities and gives you a workload-based evaluation checklist; it does not present independent benchmark scores.
Quick shortlist: compare Groq and Cerebras for hosted inference, Fireworks and Together AI for model serving options, and Modal for custom Python workloads. These are use-case starting points, not measured rankings. Benchmark the same model and request set before choosing a provider.
What Is AI Inference and Why Does It Matter?
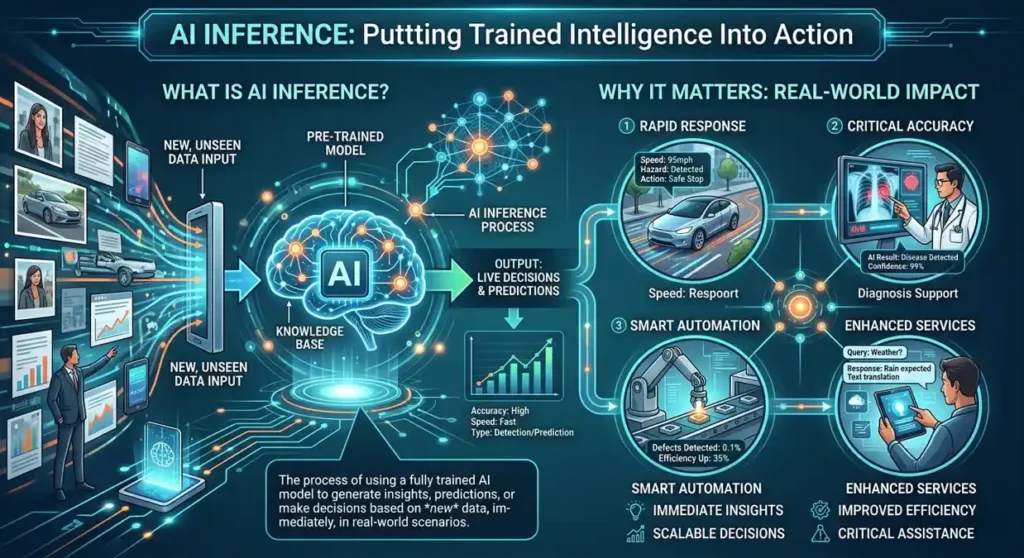
Think of training as learning a recipe and inference as using it for a new order. More precisely, inference is running a trained model on new input. A chatbot response, image classification or fraud-risk prediction can use inference, but the time and hardware needed vary widely.
How AI models are changing business workflows
Training changes a model’s parameters using data. Inference runs a trained model on new input. Both can be resource-intensive, but their costs and latency requirements depend on the task. The analogy helps explain the difference; it does not imply that training happens only once or that every inference takes milliseconds.
Inference costs depend on request volume, model size, context length and deployment type. A training-heavy research team and an application serving repeated requests will have different budgets. Compare your own usage and vendor billing data rather than applying an unsourced industry-wide percentage.
Why 2026 Is the Inflection Point
Why compare infrastructure now? An interactive chatbot needs a different latency profile from overnight document processing. A camera operating offline has different constraints from a hosted API. Define the task, acceptable error rate, concurrency and data-handling requirements before deciding between cloud, local or hybrid inference.
Infrastructure options include general-purpose GPUs, specialised inference services and on-device accelerators. Select an architecture by supported models, required accuracy, capacity, connectivity and total cost. A hardware category does not establish a universal speed or cost winner.
How to Evaluate AI Inference Vendors
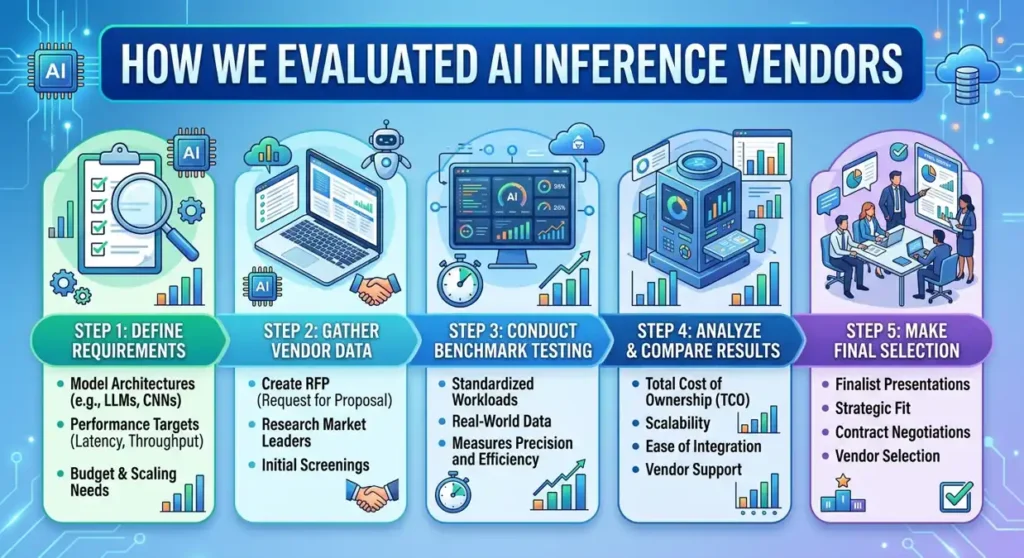
Evaluation method: this is a documentation-based shortlist, not a hands-on benchmark report. For your pilot, use the same model/version, precision, prompts, context and output lengths. Record time to first token, p50/p95/p99 latency, completed requests, errors, output quality and total billed cost. Test warm and cold requests and the concurrency you expect in production.
Latency
Time to first token and tokens-per-second under real production load.
Throughput
How many concurrent requests the platform handles before latency degrades.
Cost per Token
Total spend including compute, networking, and management overhead.
Deployment Flexibility
Support for custom models, private deployment, quantization, and hybrid setups.
Edge Support
Ability to serve beyond cloud into mobile, embedded, and IoT environments.
Top Innovative AI Inference Vendors in 2026
The providers below are organised by deployment approach and use case. The order is not a measured performance ranking. Confirm features for your exact model and service tier in the official documentation before committing.
Groq: its API offers hosted model inference with an OpenAI-compatible interface. Check the supported model, rate limits and service tier before a latency trial.
Fireworks AI: offers serverless inference, dedicated GPU deployments and training options. Compare pay-per-token access with the capacity and maintenance requirements of a deployment.
Cerebras: offers a hosted inference API built around its specialised hardware. Evaluate output quality and tail latency for an available model rather than assuming a universal tokens-per-second figure.
Together AI: offers model inference and deployment workflows. Check serverless versus dedicated availability for your model, fine-tuning needs and operational controls.
Modal: provides infrastructure for Python workloads, including custom model serving. Account for GPU runtime, scaling and idle/cold-start behaviour as well as model performance.
These descriptions summarise the official vendor documentation. No independent score out of 100 or hands-on speed result is claimed here.
Vendor Selection Comparison: Updated October 2026
| Provider | Consider when | Check before buying |
|---|---|---|
| Groq | Hosted model API fits your application | Exact model, service tier, limits and tail latency |
| Fireworks AI | Serverless or dedicated model serving | Input/output rates, deployment cost and precision |
| Cerebras | Specialised hosted inference | Available model, output quality and capacity |
| Together AI | Inference with deployment/training options | Model availability and serverless/dedicated pricing |
| Modal | Custom Python model serving | GPU runtime, scaling, cold starts and maintenance |
| AWS SageMaker | Your deployment already uses AWS | Endpoint, instance, networking and scaling costs |
| Google Vertex AI | Your deployment already uses Google Cloud | Model/region availability, quotas and data handling |
Cloud and Edge Platforms for AI Inference Efficiency
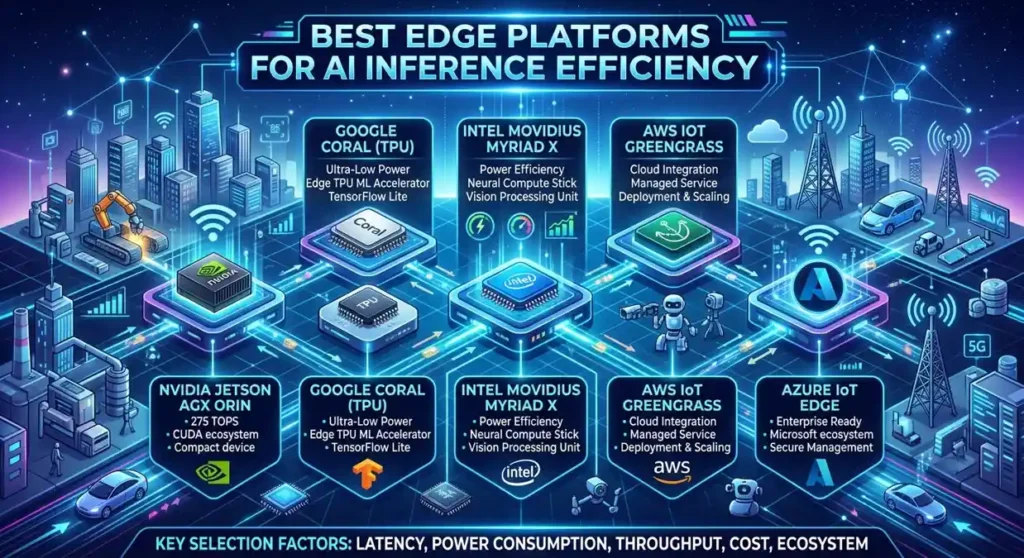
Cloud inference, network-hosted edge services and on-device inference solve different problems. Compare latency, connectivity, model support, data flow and operating cost. Offline processing can be useful when the device has enough resources; it does not make every local application automatically private.
Cloudflare Workers AI is a hosted service across Cloudflare’s network; model and execution-location availability vary. It is not equivalent to running a model offline on a user’s device.
NVIDIA Jetson is an on-device platform for embedded applications. Match the exact module, memory, software support and power profile to the model you intend to run.
Qualcomm AI Hub helps developers optimise and deploy supported models for Qualcomm-powered devices. Check the target device and runtime rather than treating a headline TOPS figure as application performance.
AWS Inferentia2 is a cloud inference accelerator used in Inf2 instances. Account for model conversion, supported operators, instance utilisation and engineering effort; a vendor’s example savings are not guaranteed savings for your application.
Apple’s Neural Engine can support local inference through compatible software and models. A cloud-backed feature has a different data flow from a fully local model; review the actual application behaviour.
Hailo-8L is an embedded inference accelerator. Check supported model conversion, available memory and measured power/throughput for the full application rather than comparing TOPS alone.
What to Look for in an AI Inference Vendor
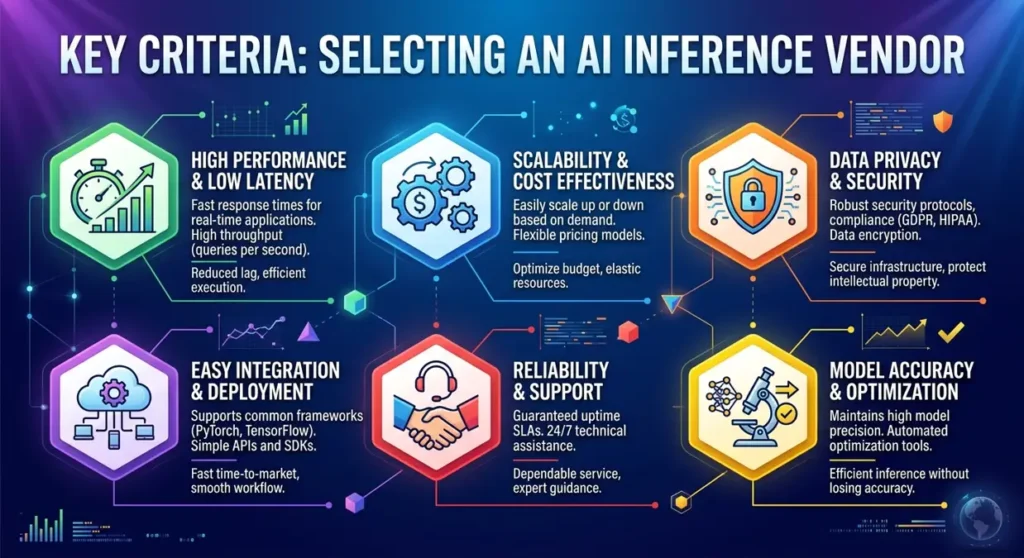
Vendor selection isn’t just a technical decision — it’s a product architecture decision. The wrong choice compounds. Here’s what actually deserves weight when you’re evaluating options.
1. The SLA Behind the Latency Number
Ask which latency metric a vendor reports and what it includes. Record time to first token and total response time, plus p95/p99 under your expected concurrency. Check availability commitments, rate limits, error handling and how model updates affect a pinned version. A median result alone does not describe slow requests.
2. Model Coverage vs Model Depth
Model coverage is a starting filter. Confirm the exact version, precision, context limit, tool-calling and structured-output support you need. Then evaluate its quality and serving behaviour; a larger catalogue does not establish better performance for your model.
3. Quantization Support and Its Actual Impact
Quantization can reduce memory requirements and change serving performance, but quality and cost effects depend on the model, hardware and task. Evaluate the quantized version against the original on representative examples, including difficult cases. Do not assume a fixed saving percentage or acceptable quality loss.
4. Observability and Debugging Tools
When inference quality degrades in production — and it will — you need to know why. Does the platform provide token-level logging, request tracing, cost attribution per request, and integration with tools like Langfuse or Helicone? Platforms that treat observability as an afterthought will cost you real time when something goes wrong.
5. The Fine-Tuning to Serving
If your roadmap includes fine-tuning, evaluate whether the inference vendor also handles fine-tuned model serving, or whether you’re committing to a two-vendor architecture. The operational overhead of managing separate training and inference vendors is real and often underestimated in initial planning.
AI Inference Speed, Cost, and Performance Factors
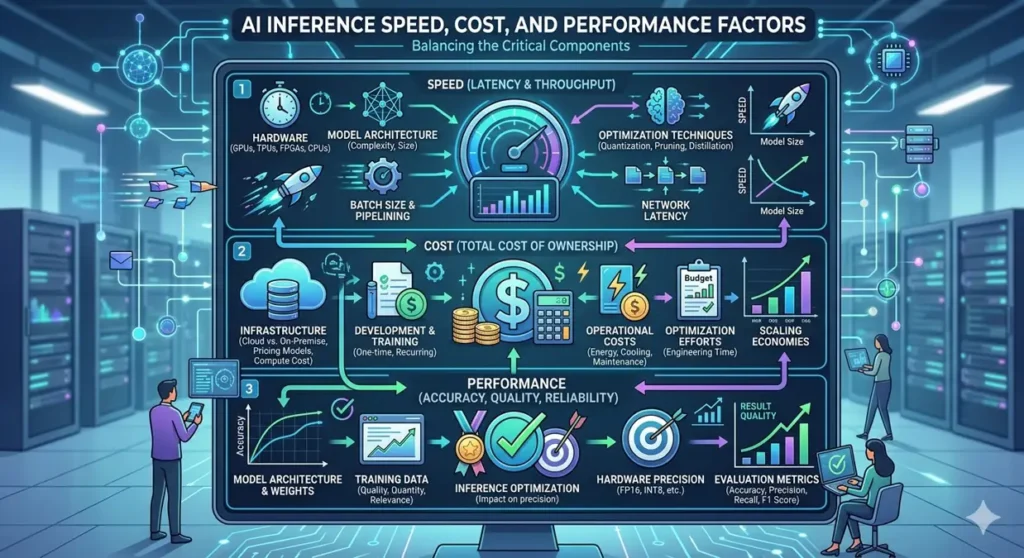
Latency, throughput, quality and cost interact. Batching may improve utilisation while increasing queueing delay; a smaller model may be faster while missing difficult cases. Measure cost per successful task as well as token price, and keep your quality threshold explicit.
| Metric | What to measure | Typical tradeoff to test |
|---|---|---|
| Time to first token | Network, prompt processing and queueing | Dedicated capacity may cost more |
| Output speed | Tokens per second with the same model and settings | Measure quality and latency together |
| Total cost | Input/output, cache, capacity, networking and retries | Low token price may not mean low task cost |
| Throughput | Successful completed requests at expected concurrency | Batching can increase queueing delay |
| On-device efficiency | Quality, memory, power and offline operation | Hardware and model-size limits |
Speculative decoding uses a draft model to propose tokens that a target model verifies. Its benefit depends on acceptance rate, batch size, model pairing and implementation. Compare actual latency, throughput and output behaviour; do not assume a fixed speed multiplier.
Cost Optimization Three Practical Strategies
Tiered routing: send simpler tasks to a suitable smaller model and escalate uncertain cases. Compare accuracy, escalation rate and total cost against a single-model baseline. Savings depend on the real task mix and are not guaranteed.
Prompt caching: check whether your provider supports it, which repeated prefixes qualify, retention rules and cache-read/write charges. A repeated system prompt may reduce work, but it is not automatically processed or billed only once forever.
Batch inference: use an eligible batch service for work that can wait, such as document processing. Compare its completion deadline, limits and price with synchronous requests. Spot capacity is a separate deployment choice and may be interrupted; design retries and recovery accordingly.
Enterprise vs Edge AI Inference Solutions
These are genuinely different problems — different hardware, different constraints, different failure modes, and different cost models. Many companies need both, which makes the architecture decision interesting.
| Decision | Hosted cloud inference | On-device inference |
|---|---|---|
| Connectivity | Usually needs a working network connection | Can work offline if the complete task runs locally |
| Model fit | Check hosted version, precision and limits | Check available memory, runtime and model conversion |
| Data handling | Review retention, region, access and subprocessors | Review telemetry, syncing and any cloud fallback |
| Updates | Version changes need compatibility tests | Device rollout and rollback need planning |
| Costs | API/capacity, networking, storage and operations | Hardware, power, development and maintenance |
| Latency | Measure network, queueing and serving together | Measure the complete task on the target device |
| Reliability | Plan limits, retries and provider outages | Plan thermal, power and hardware constraints |
The Hybrid Architecture Emerging in 2026
A hybrid design routes suitable tasks locally and sends cases that need a larger model to a hosted service. Set escalation rules, protect transferred data and handle network failure. The share processed locally, quality and total cost must be measured for your workload; no universal local/cloud percentage applies.
Final Thoughts on the Best Inference Vendors
There is no single best inference vendor for every workload. Choose a shortlist from your deployment requirements, compare documented features and then run a controlled pilot. Recheck model availability, prices, quotas and reliability as your application changes.
Best fit when response speed is central to product experience.
Strong balance of affordability, open-model support, and production readiness.
Useful when collaboration, analytics, and deployment workflow all matter.
Great for teams that want more control over inference code without heavy DevOps.
Still one of the strongest platforms for embedded and physical AI systems.
A practical path for AWS-native organizations looking to reduce GPU dependence.
Use an adapter for provider-specific requests, keep model versions and configuration explicit, and maintain quality tests before switching. An OpenAI-compatible endpoint can simplify integration, but differences in tools, streaming, structured output, limits and billing still require validation. Revisit the vendor when measured quality, reliability or cost no longer meets your requirements.
Read More: Best LLM for Coding in 2026
What are the top innovative AI inference vendors right now?
A useful shortlist is Groq, Cerebras, Fireworks AI, Together AI and Modal. Each provides a different serving or deployment approach. Compare the exact model, service tier, quality, latency and total cost for your application; this guide does not rank them by an independent benchmark.
What is the best edge platform for AI inference efficiency?
Choose by the target: embedded hardware, a mobile device or a network-hosted service. NVIDIA Jetson, Qualcomm AI Hub and Hailo address different device/runtime needs, while Cloudflare Workers AI is hosted. Confirm model compatibility, offline requirements, memory and power on your actual device.
How fast is Fireworks AI inference speed compared to other vendors?
There is no comparable universal speed figure across different models, precision, context lengths and concurrency. Test Fireworks and alternatives using the same request set and model settings. Report time to first token, response time, output speed, quality and billed cost separately.
What is the difference between AI training and AI inference infrastructure?
Training changes model parameters using data; inference runs the trained model on new inputs. Training prioritises model development, while production serving also needs predictable latency, throughput, reliability and cost. The balance of spending varies by organisation and workload.
How do I choose between cloud inference and edge inference?
Consider offline operation, target-device resources, acceptable latency, data flow and deployment maintenance. Cloud services can offer hosted models and central management; local inference needs a model that fits the device. A hybrid approach also needs clear escalation and network-failure behaviour.
Hardware references: Hailo-8L product brief and AWS Inf2 documentation. Inferentia2 is cloud infrastructure, while Hailo-8L is an on-device accelerator. Compare throughput and prices using the same model, precision, context length, and concurrency; results from different workloads are not directly comparable.
